Blaze ASR: High-Performance GPU Audio Transcription GUI
Ultra-fast GPU-accelerated desktop speech-to-text transcriber engineered by Christopher Lazok, featuring Faster Whisper, Cohere Transcribe, CUDA optimization, BYOM model integration, and automated speaker diarization.
Blaze ASR: High-Performance GPU Audio Transcription GUI
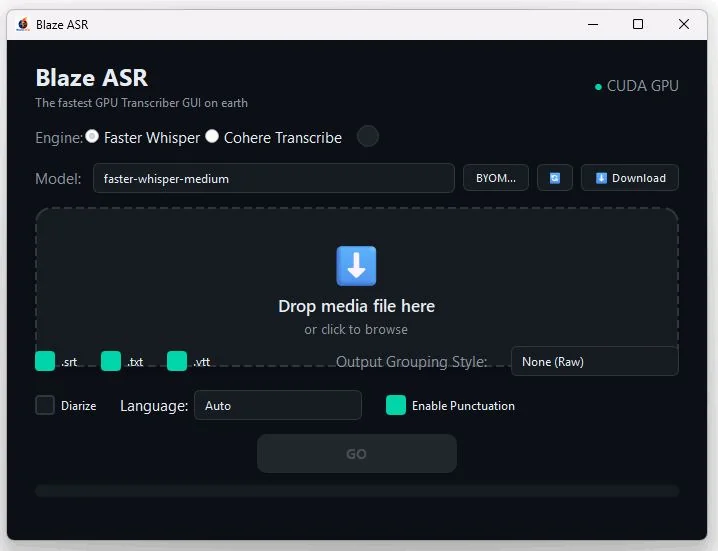
The fastest GPU Transcriber desktop application on earth. Engineered by Christopher Lazok with Faster Whisper, Cohere Transcribe, CUDA FP16/INT8 inference, Bring Your Own Model (BYOM) support, and automated speaker diarization.
⚡ Architectural Overview
Blaze ASR is an offline-first, high-throughput desktop speech-to-text transcription studio designed to bypass slow cloud API rate limits and eliminate recurring per-minute audio processing fees. By coupling Systran's CTranslate2-backed Faster Whisper engine with NVIDIA CUDA GPU acceleration, Blaze ASR achieves transcription speeds upwards of 15x to 30x real-time.
1. Dual Transcription Engine Architecture
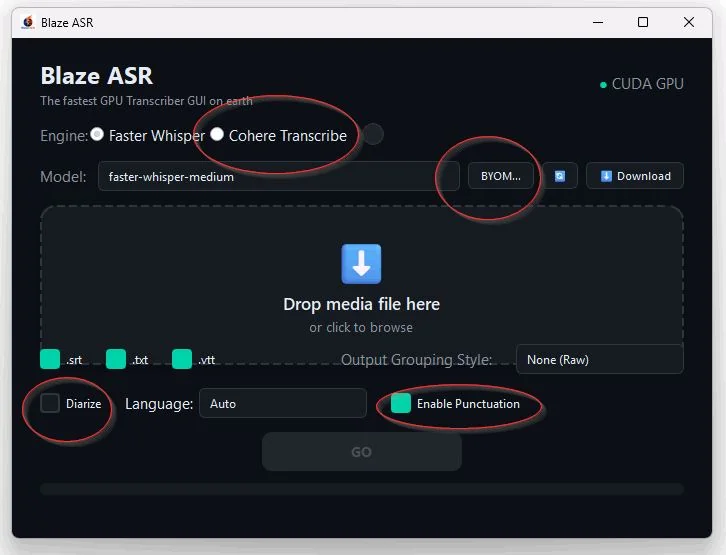
- Faster Whisper (CTranslate2 Core): Vectorized FP16 and INT8 quantized inference executing directly on NVIDIA CUDA Tensor Cores for maximum token-per-second speech decoding.
- Cohere Transcribe Bridge: Pluggable transcription backend supporting specialized multilingual models and edge embeddings.
- BYOM (Bring Your Own Model): Dynamic model loader supporting arbitrary HuggingFace Whisper checkpoints and local fine-tuned weights without recompilation.
2. Multi-Model Downloader & Weight Management
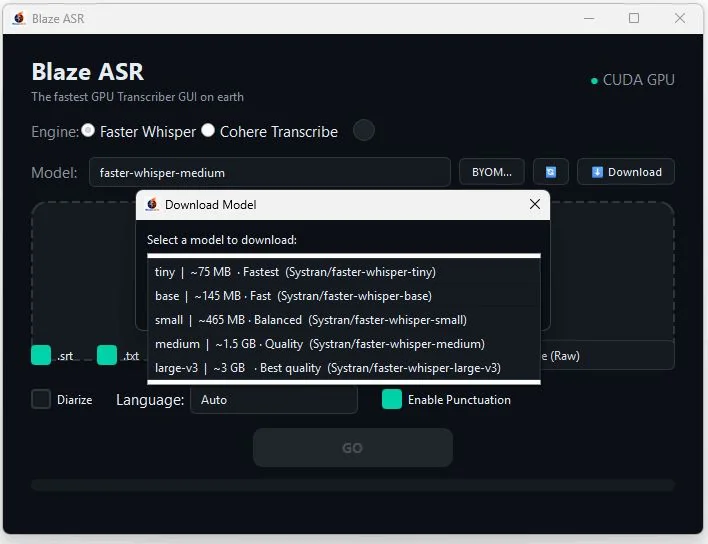
Built-in automated weight management with instant download and local caching:
tiny(~75 MB) · Ultra-fast preview and live streaming transcriptionbase(~145 MB) · Rapid conversational transcriptionsmall(~465 MB) · Balanced accuracy-to-speed profilemedium(~1.5 GB) · High-precision enterprise transcriptionlarge-v3(~3 GB) · State-of-the-art acoustic accuracy for technical vocabulary and accents
3. Audio Ingestion & Export Pipeline
- Drag-and-Drop Ingestion: Zero-configuration drag-and-drop ingestion supporting MP3, WAV, MP4, MKV, FLAC, and AAC media files.
- Timestamped Subtitle Generation: Instant export to industry-standard
.srt,.vtt, and raw cleaned.txttranscripts. - Speaker Diarization: Multi-speaker clustering and segmentation attributing timestamps to distinct conversational speakers.
- Punctuation Restoration & Truecasing: Deep learning punctuation capitalization pass preventing disjointed raw ASR run-ons.